
Technical SEO is the code- and server-level setup that helps search engine crawlers move through pages without errors, understand them and add them to the index. Four basic tools handle this job: the robots.txt file, the sitemap.xml file, the canonical tag and 301/302 redirects. Below we go through each one: what it does, what its syntax looks like and which mistakes most often break indexing.
Key points in 30 seconds
- robots.txt controls crawling: it tells crawlers which sections they don’t need to scan.
- sitemap.xml is a list of important URLs that helps the search engine discover pages faster.
- The canonical tag rel=”canonical” specifies the main version of a page and consolidates duplicates.
- A 301 redirect is a permanent move that passes link equity; a 302 is temporary.
- A mistake in any of these elements can block the entire site from indexing, so the setup should be checked after every release.
Crawling and indexing: how a search engine processes a site
Before a page appears in search, it goes through two stages. Crawling is the process where a search engine bot follows links, downloads the HTML of pages and discovers new URLs. Indexing is the next step: the system analyzes the content and adds the page to its database, after which it can be shown in the SERP.
It’s important to keep these stages apart: a page can be crawled but not indexed, for example if it has a noindex tag or is treated as a duplicate. On large sites, crawl budget comes into play: the limited number of URLs a bot is willing to crawl per visit. The technical tools below help direct that budget to important pages instead of wasting it on service pages.
robots.txt: what it is and how to set it up
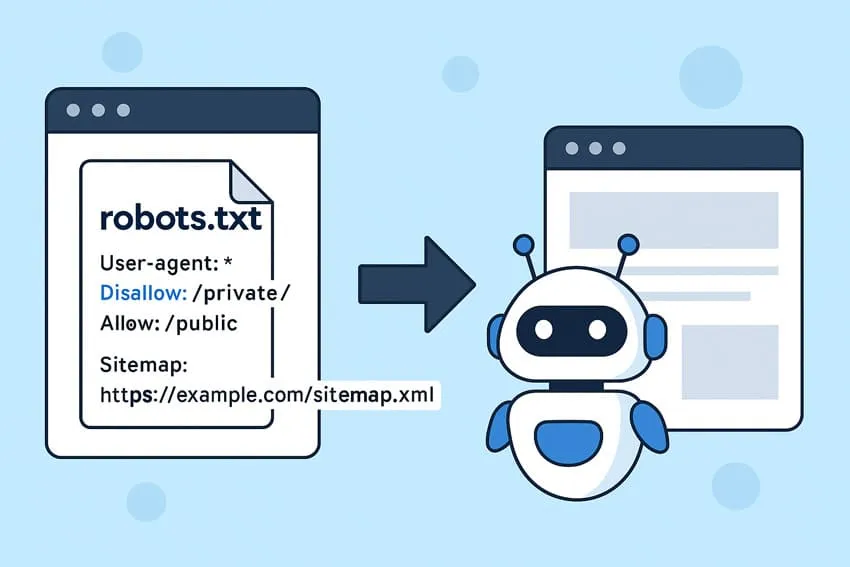
robots.txt is a text file in the site root (available at site.com/robots.txt) that tells search engine crawlers which sections they don’t need to crawl. It controls crawling, not indexing, and that’s a fundamental difference.
The basic syntax consists of the directives User-agent (which bot the rule applies to), Disallow (what to block), Allow (what to permit) and a pointer to the sitemap:
User-agent: *
Disallow: /admin/
Disallow: /cart/
Allow: /
Sitemap: https://site.com/sitemap.xml
A common and dangerous mistake is leaving the directive Disallow: / (with a single slash), which blocks the whole site from crawling. This often happens when robots.txt is copied from a staging version to production. Another nuance: a page blocked in robots.txt can still end up in the index if external links point to it. To remove a page from search, use the noindex meta tag or a canonical tag, not robots.txt.
Sitemap.xml: a site map for crawlers
Sitemap.xml is an XML file listing the important URLs you want to see in the index. It doesn’t guarantee indexing and doesn’t directly affect rankings, but it speeds up page discovery, especially on new and large sites with deep nesting.
Besides URLs, the sitemap can include the last modified date (lastmod), which helps the crawler see which pages have been updated. Once created, the sitemap is submitted to Google Search Console and its URL is added to robots.txt.
Typical mistakes: adding pages blocked from indexing (noindex), non-existent URLs returning 404 or redirects to the sitemap, and forgetting to update it after the site structure changes.
The canonical tag: how to get rid of duplicates
The canonical tag rel=”canonical” tells the search engine which version of a page is the main one when identical or nearly identical content is available at several URLs. It goes in the <head> section:
<link rel=”canonical” href=”https://site.com/tovar/” />
Canonicals solve the problem of duplicates caused by catalog filters and sorting, UTM parameters, pagination, www and non-www versions, http and https. Good practice is to put a self-referencing canonical tag on every page (the page points to itself).
Common mistakes: the canonical points to a page with a redirect or a 404, every page on the site points to the homepage, canonicals conflict with a noindex tag. More on finding and fixing duplicates in the article on duplicate content and keyword cannibalization.
301 and 302 redirects: what’s the difference
A redirect automatically sends users and bots from one URL to another. For SEO, choosing the right type is critical.
| Parameter | 301 (permanent) | 302 (temporary) |
| Purpose | The page has moved permanently | The page is temporarily unavailable at this URL |
| Link equity | Passes almost all link equity | Link equity is passed only partially |
| What happens in the index | The old URL is replaced by the new one | The old URL stays in the index |
| When to use | URL change, www consolidation, http→https, migration | Promotion, A/B test, maintenance |
The main mistake is using a 302 where a 301 is needed (for a permanent move): link equity isn’t consolidated and the old URL keeps competing with the new one. Redirect chains (URL A → B → C) are also dangerous: they waste crawl budget and lose some link equity at every hop. To learn how to move a site without losing rankings, read our guide on site migration.
Common technical SEO mistakes
- Disallow: / in robots.txt, accidentally carried over from a staging server, blocks the entire site.
- A noindex meta tag forgotten after development: pages don’t make it into search.
- All canonicals point to the homepage: important pages drop out of the index.
- Redirect chains and loops instead of one direct 301.
- The sitemap includes blocked, non-existent or redirecting URLs.
- Mixed http/https content after switching to the secure protocol.
How to check your setup
Most problems can be spotted in half an hour if you know where to look.
robots.txt: open site.com/robots.txt in a browser and make sure important sections aren’t blocked; Search Console has a dedicated testing tool.
Indexing: in Google Search Console, check the “Page indexing” report and use the URL Inspection tool. If pages aren’t getting indexed, work through the causes with the checklist in our article on why a site isn’t getting indexed.
Redirects and canonicals: run the site through a crawler; it will show all redirect chains, response codes and canonical tags in bulk. Sitemap: check it with a validator and make sure it opens and contains only working URLs.
Regular diagnostics are easiest to run in Search Console; how to set it up and read the reports is described in a separate guide on setting up Google Search Console.
All these checks are part of a technical SEO audit. When there are many pages, catching errors by hand takes a long time and it’s easy to miss something; it’s more systematic to order a technical SEO audit, which will find sections blocked from indexing, broken redirects and duplicates and give you a prioritized list of fixes. Want to make sure the technical side of your site isn’t holding back promotion? Leave a request for an SEO audit, and we’ll check robots.txt, the sitemap, redirects and canonicals for your project. The overview article what is link building also helps you see where technical SEO fits in the bigger picture.